Edge Release Notes - September 2026
The content on this site may have changed or moved since you last viewed it. As a result, some of your bookmarks may become obsolete. Therefore, we recommend accessing the latest content via the Hevo Docs website.
In this Release
Early Access Features
Activate
Support for Reverse ETL with Activate
NewHevo now supports Activate, which enables Reverse ETL (Extract, Transform, and Load) to send data from Amazon Redshift and Snowflake to HubSpot.
With this feature, you can connect a supported Source, define the data you want to send using an SQL query or a selected table, and connect a HubSpot Target to receive it. You can control how existing records are synchronized, map your data to fields in HubSpot, and schedule or manually trigger syncs. You can also monitor each run and download an error report for troubleshooting.
You can contact your Hevo account executive or the Support team to enable Activate for your team.
Refer to the Early Access page for the complete list of features available for early access.
Sources
Build Connectors for REST-Based Sources with Connect AI
NewHevo now lets you build connectors for your REST (Representational State Transfer)-based Sources that are not currently supported. Connect AI only needs the Source’s API documentation and connection credentials to identify and validate the objects that can be synced. This gives you a ready-to-use connector with the validated objects, allowing you to create a Pipeline and replicate data from your Source without writing code or managing infrastructure. Once published, the connector is managed and maintained like any other Source in Hevo.
You can contact your Hevo account executive or the Support team to enable Connect AI for your team.
Refer to the Early Access page for the complete list of features available for early access.
New and Changed Features
Destinations
Support for SUPER Data Type in Amazon Redshift
EnhancedHevo now maps JSON data from Source objects to the SUPER data type in the Destination tables, aligning with Redshift’s recommended data type for storing semi-structured data. This applies only to new field mappings.
Earlier, Hevo mapped JSON data to the VARCHAR data type. If a Destination column was already created as VARCHAR, Hevo does not automatically convert it to SUPER. To load existing JSON data as SUPER, resync the object with the Drop and Load option enabled to re-create the Destination table and load the historical data.
Getting Started
Support for the EU2 (London) Region
NewHevo is now available in the EU2 region, hosted on AWS in London (eu-west-2). To use this region, select it from the region selector, or go directly to https://eu2.hevodata.com/. You can create Edge Pipelines and Destinations in this region to host your data closer to your infrastructure or meet your compliance requirements.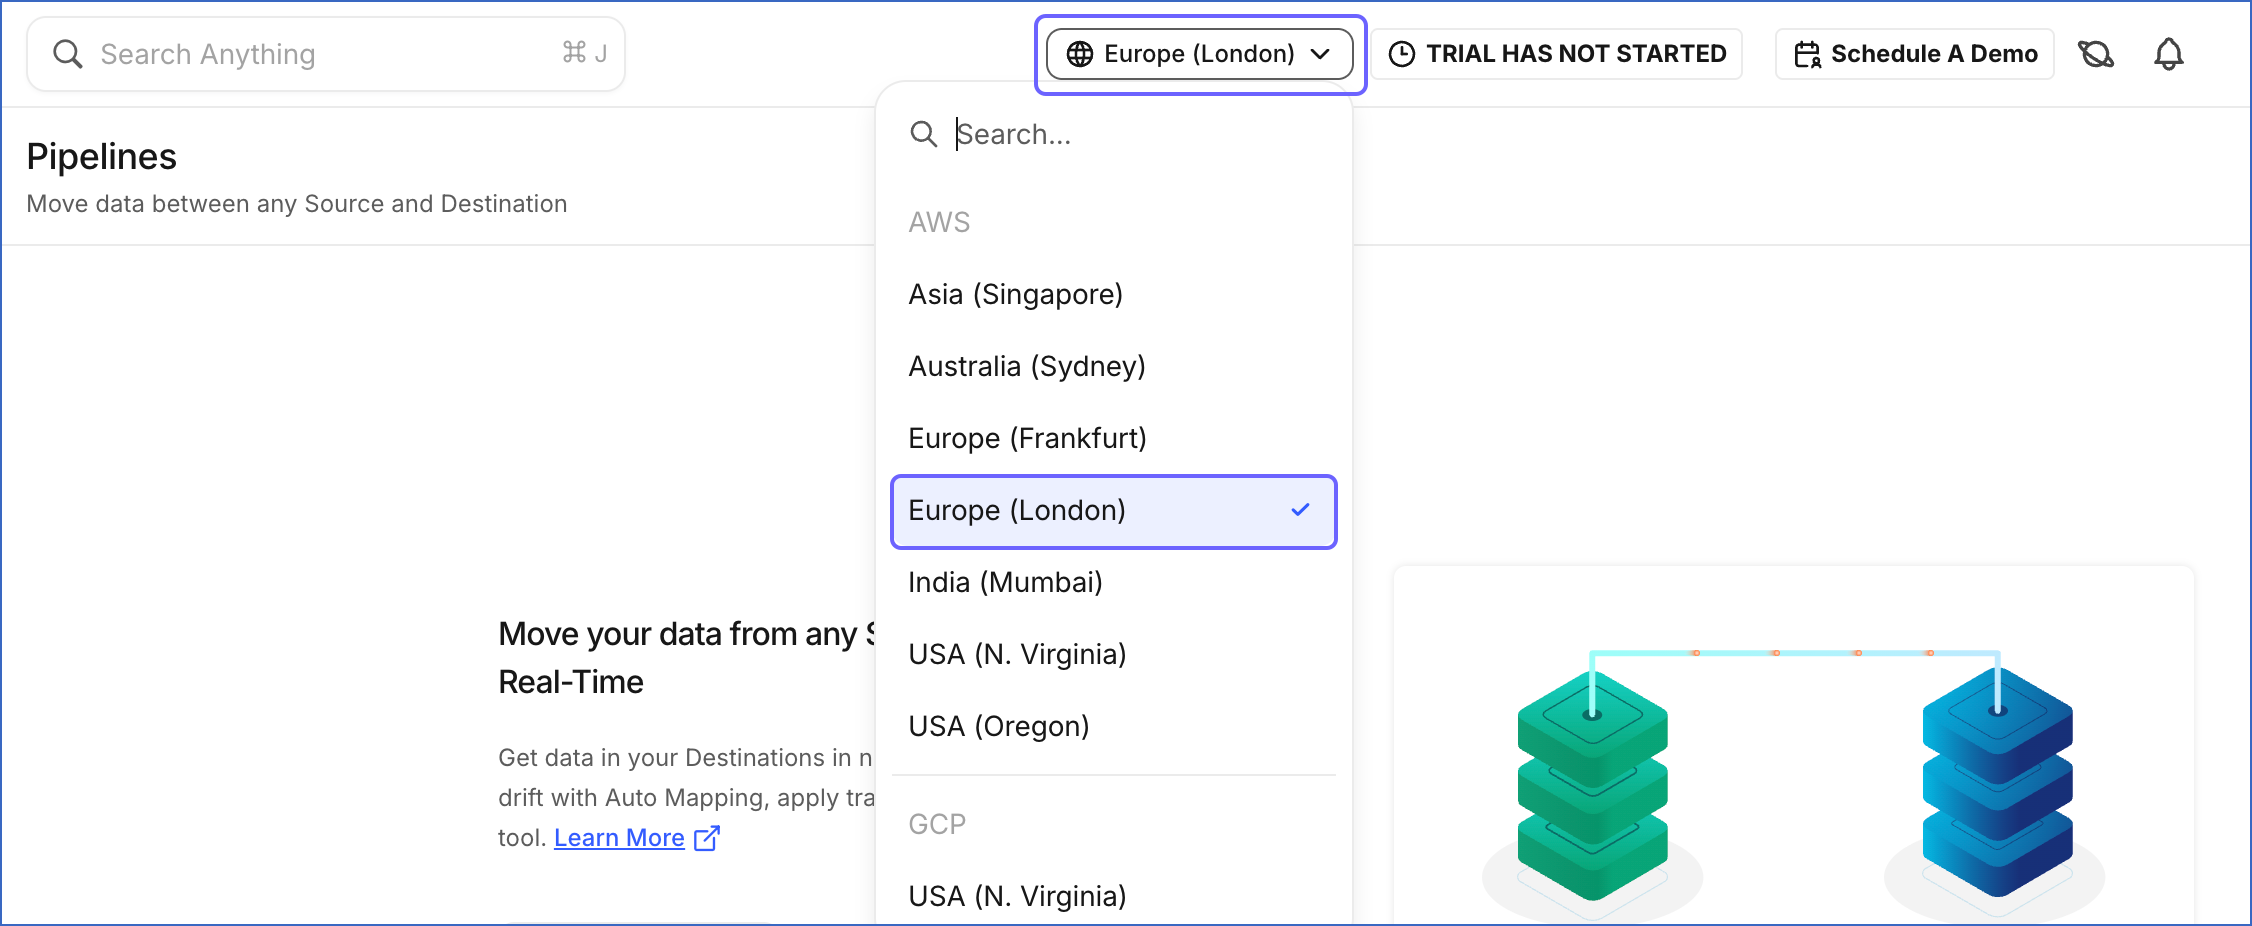
Note: Standard Pipelines and Destinations are not supported in the EU2 region.
Selecting your Hevo Region →Sources
Support for Tempo as a Source
NewHevo now supports Tempo as a Source for creating Pipelines. Tempo is a suite of project, product, and portfolio management applications built directly into Jira, unifying time tracking, resource capacity planning, financial management, and reporting on a single platform. You can replicate data from your Tempo account, including Worklogs, Plans, and Projects, into your Destination.
Tempo →Support for Facebook Pages as a Source
NewHevo now supports Facebook Pages as a Source for creating Pipelines. Facebook Pages is Meta’s platform that lets businesses, brands, and public figures create a public presence, publish posts, and engage with their audience. You can replicate data from your Facebook Pages account, including Page and Post details, along with daily and lifetime performance metrics for Pages and Posts, into your Destination.
Facebook Pages →Support for Braintree Payments as a Source
NewHevo now supports Braintree Payments as a Source for creating Pipelines. Braintree is a payments platform that enables businesses to accept, process, and manage online and in-app payments across methods such as credit and debit cards, PayPal, and digital wallets. You can replicate data from your Braintree Payments account, including transaction, subscription, and registered customer details, along with dispute and merchant account information, into your Destination.
Braintree Payments →Support for Klaviyo v2 as a Source
NewHevo now supports Klaviyo v2 as a Source for creating Pipelines. Klaviyo v2 is a marketing automation platform that consumer brands use to manage email, SMS, and other messaging channels from a single account. You can replicate data from your Klaviyo account, including campaign, flow, and form details, along with profile, event, list, and segment data, into your Destination.
Klaviyo v2 →Support for Google Search Console as a Source
NewHevo now supports Google Search Console as a Source for creating Pipelines. Google Search Console is Google’s free web service that helps you monitor, maintain, and troubleshoot your site’s presence in Google Search results. You can replicate data from your Google Search Console account, including keyword, page, and site-level search performance reports, along with Pages and Sitemap details, into your Destination.
Google Search Console →