Activate (Edge)
Activate is currently available for Early Access. Please contact your Hevo account executive or the Support team to enable it for your team. Alternatively, request for early access to try out one or more such features.
Activate is Hevo’s Reverse ETL (Extract, Transform, and Load) solution for sending data from your data warehouses to the business applications where your teams work. Unlike a Pipeline, which brings data into your data systems for analysis, Activate sends data out of those systems, so your teams can act on the same data as your analysts.
You define the data you want to send by writing an SQL query or selecting a table. You can map that data to fields in the Target application, control how existing records are handled, and schedule or manually trigger syncs. Activate keeps the Target application in sync with your data, without requiring anyone to export and upload files manually.
For example, you can send customer records that have been cleaned, combined, or enriched in your data warehouse to HubSpot, so your sales and marketing teams can use that data in their day-to-day work.
With Activate, you can:
-
Connect a Source: Connect to the data system that contains the data you want to send.
-
Define a dataset: Select a table or write an SQL query to specify the rows and columns you want to send.
-
Connect a Target: Connect to the business application that receives your data.
-
Control sync behavior: Choose how Activate handles the records that already exist in the Target object, such as creating, updating, or deleting records, depending on what the Target supports.
-
Map your data: Map dataset columns to fields in the Target object, and define how existing records are matched.
-
Schedule or trigger syncs: Run syncs on a predefined or custom schedule, or trigger them manually when needed.
-
Monitor syncs: Review each run to see how many records were synced, failed, or skipped, and download an error report to troubleshoot failed records.
Activate in the Reverse ETL Workflow
The following diagram illustrates how Activate fits into the Reverse ETL workflow:
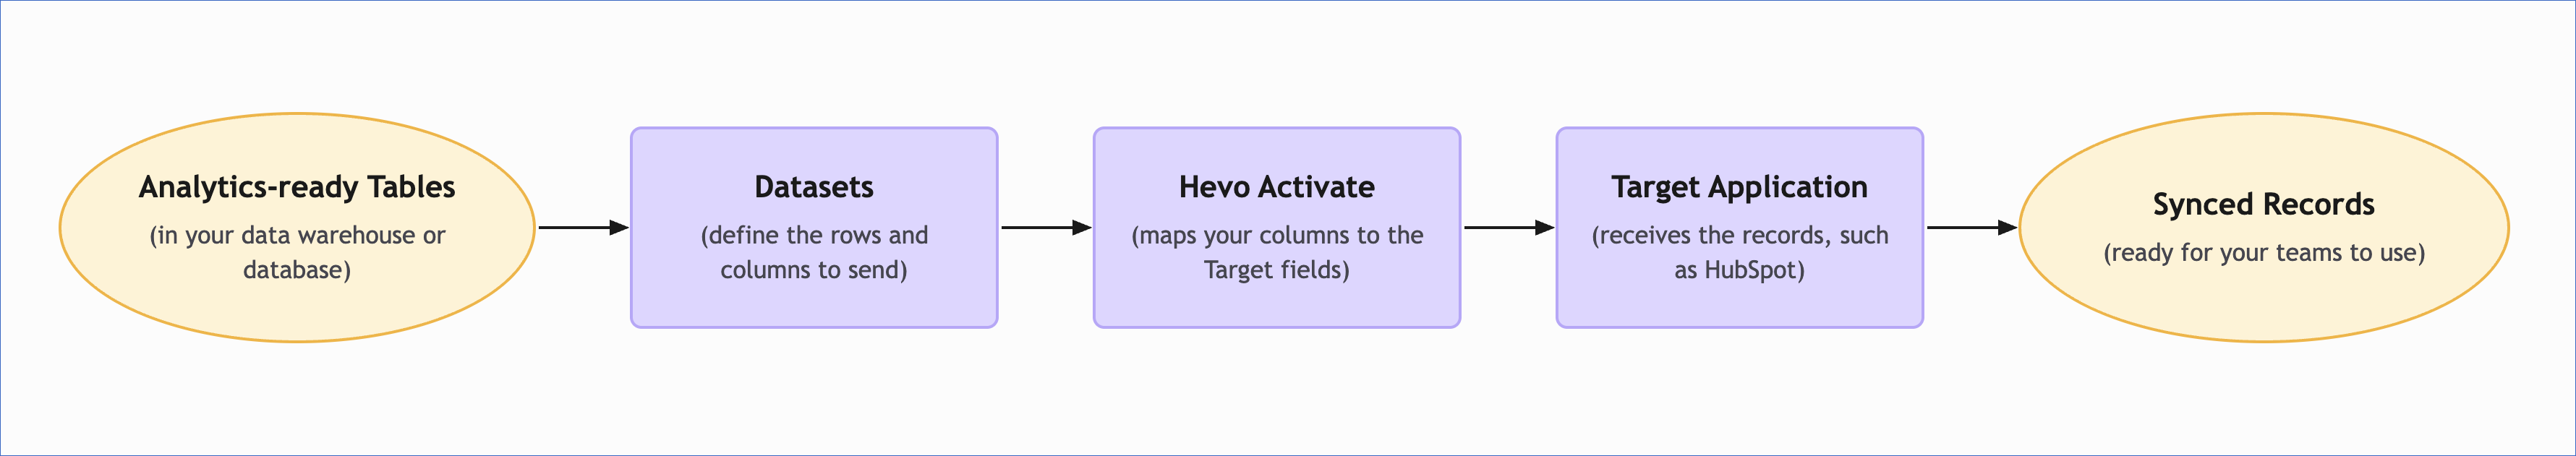
Activate handles the three steps of the Reverse ETL process:
-
Extract: Activate extracts the rows defined by your dataset from your data system.
-
Transform: Activate maps your dataset columns to fields in the Target object.
-
Load: Activate sends the mapped data to the Target application according to your sync schedule.
This is the opposite of the ELT (Extract, Load, and Transform) process. In an ELT workflow, Pipelines bring data from your Sources into your data systems, where Transformations can prepare the data for analysis. With Activate, you send that prepared data from your data system to the business applications where your teams need it.
Because Activate reads from your existing data system, you can send data that your Pipelines have already loaded and your Transformations have already prepared.
Core Concepts
The core structure of Activate defines how data is selected from your data systems and sent to your business applications. The following terms describe each part of that structure and the settings that control each Activation sync:
-
Source: Connects to the data system that contains the data you want to send.
-
Dataset: Defines the data you want to send from a Source. You can create a dataset by writing an SQL query or selecting a table. The dataset contains the rows and columns that Activate sends to the application.
-
Target: Connects to the business application that receives your data.
-
Target Object: Represents the type of record in the Target application that receives your data, such as contacts or companies in HubSpot. The Target object determines the fields available for mapping and the sync behaviors you can use.
-
Activation: Connects a dataset to a Target object and defines how and when the data is synced. Each time an Activation executes, it creates a run.
-
Run: Represents one execution of an Activation. A run shows whether the sync completed successfully and reports how many records were synced, failed, or skipped. You can also view the reasons for failed records.
-
Sync Behavior: Defines what happens to records in the Target object when an Activation runs. You can create new records, update existing records, do both, delete records that match your dataset, or keep the Target object in sync with your dataset. The behaviors you can use depend on the Target object you select. Read Select the Target for the available sync behaviors and an example that shows which records each one creates, updates, or deletes.
-
Sync Key: Helps identify an existing record in the Target object. It uses a column from your dataset and a field in the Target object that contain the same unique value. Activate uses this value to determine whether a dataset row matches an existing record before applying the sync behavior. You can select only the fields that the Target application treats as unique.
-
Field Mapping: Specifies where each dataset column should be written in the Target object. You can map the columns you want to send to fields in the Target object. Dataset columns that you do not map are not sent. A column that you map but that has no value is sent as an empty value, which clears that field in the Target object.
-
Sync Schedule: Specifies when an Activation runs. You can choose a predefined schedule, create a custom schedule, or run an Activation manually at any time. Read Configure the Schedule for the available schedules and the time zone that Activate uses.
Key Features
Activate provides the following features to help you control what data is sent, where it goes, and how it is synced:
SQL query or table selection
You can define a dataset by writing an SQL query or selecting a table. SQL queries let you filter rows, rename columns, and join tables before sending the data. If you want to send a table as it is, you can select it without writing any SQL.
Reusable datasets
A dataset is not tied to a single Activation. You can use a dataset across multiple Activations, allowing you to reuse a query or table selection when sending the same data to multiple applications.
Control over existing records
Each Activation defines how records are synced with the Target. Depending on the Target object, you can configure an Activation to create records, update existing records, do both, delete matching records, or keep that object in sync with your dataset.
Sync behavior is configured per Activation, so multiple Activations using the same dataset can handle existing records differently.
Note: The available sync behaviors depend on the Target object. Refer to the documentation for your respective Target type for the behaviors that each of its Target objects supports.
Auto-generated field mapping
While mapping fields, you can click Auto-Generate Mapping to automatically match dataset columns with fields that have the same names in the Target object. You can review the generated mappings and modify them as needed.
Flexible scheduling
An Activation can sync as often as every five minutes. You can choose one of the predefined intervals, up to once a day, or define a custom schedule using a cron expression. The first sync starts as soon as you create the Activation, and subsequent runs follow the schedule you set.
The predefined intervals are aligned to fixed clock times and not to the time at which you create the Activation. For example, a 24 Hrs schedule runs at midnight and a 1 Hr schedule runs at the start of every hour. A cron expression must contain five fields and is evaluated to the minute, so you cannot schedule a run at a specific second.
Note: Activate evaluates the predefined intervals and the cron expressions in UTC.
Incremental syncs
After the first sync, Activate sends only the rows that changed since the last successful run instead of the entire dataset, which reduces the amount of data processed during subsequent runs. This applies to both scheduled and manual runs. You can trigger a resync when you need to send the entire dataset again.
Per-run visibility
Every run records how many records were synced, failed, or skipped. You can review these results in the Sync History tab.
If records fail, you can download an error report as a CSV file. The report lists each error, the number of records affected, and a sample affected record, helping you identify and correct the underlying data before sending it again.
Supported Sources
Activate currently supports reading data only from the following Sources:
Supported Targets
Activate currently supports writing data only to HubSpot.
When to Use Activate
Use Activate when you want to:
-
Send prepared data to business applications so the teams working in them can use the same data your analysts do.
-
Keep application records synchronized with your warehouse data instead of manually exporting and importing files.
-
Send data prepared by your Transformations to the business applications that need it.